Qwen3.8-Flash-Next-AZ-Focus
Alibaba's Qwen3.8-Flash-Next, with the second-guessing turned down. About half the thinking at its default effort, the same answers, and agentic coding unchanged, on a single DGX Spark.
It stops second-guessing itself
On hard questions Qwen3.8-Flash-Next spends much of its thinking on hesitation: "Wait…","Hmm, maybe…", re-checking answers it already had. We optimised the model's weights against that habit, while leaving alone the checking it does as an agent (running tests, inspecting output before it submits). It still reasons step by step. It just loops less.
Illustration: each block is about 10 thinking tokens. The lengths match our measured averages on reasoning benchmarks (about half the thinking tokens) with accuracy within about three points. Fewer thinking tokens means less to generate, so answers generally arrive sooner.
Less thinking, same answers
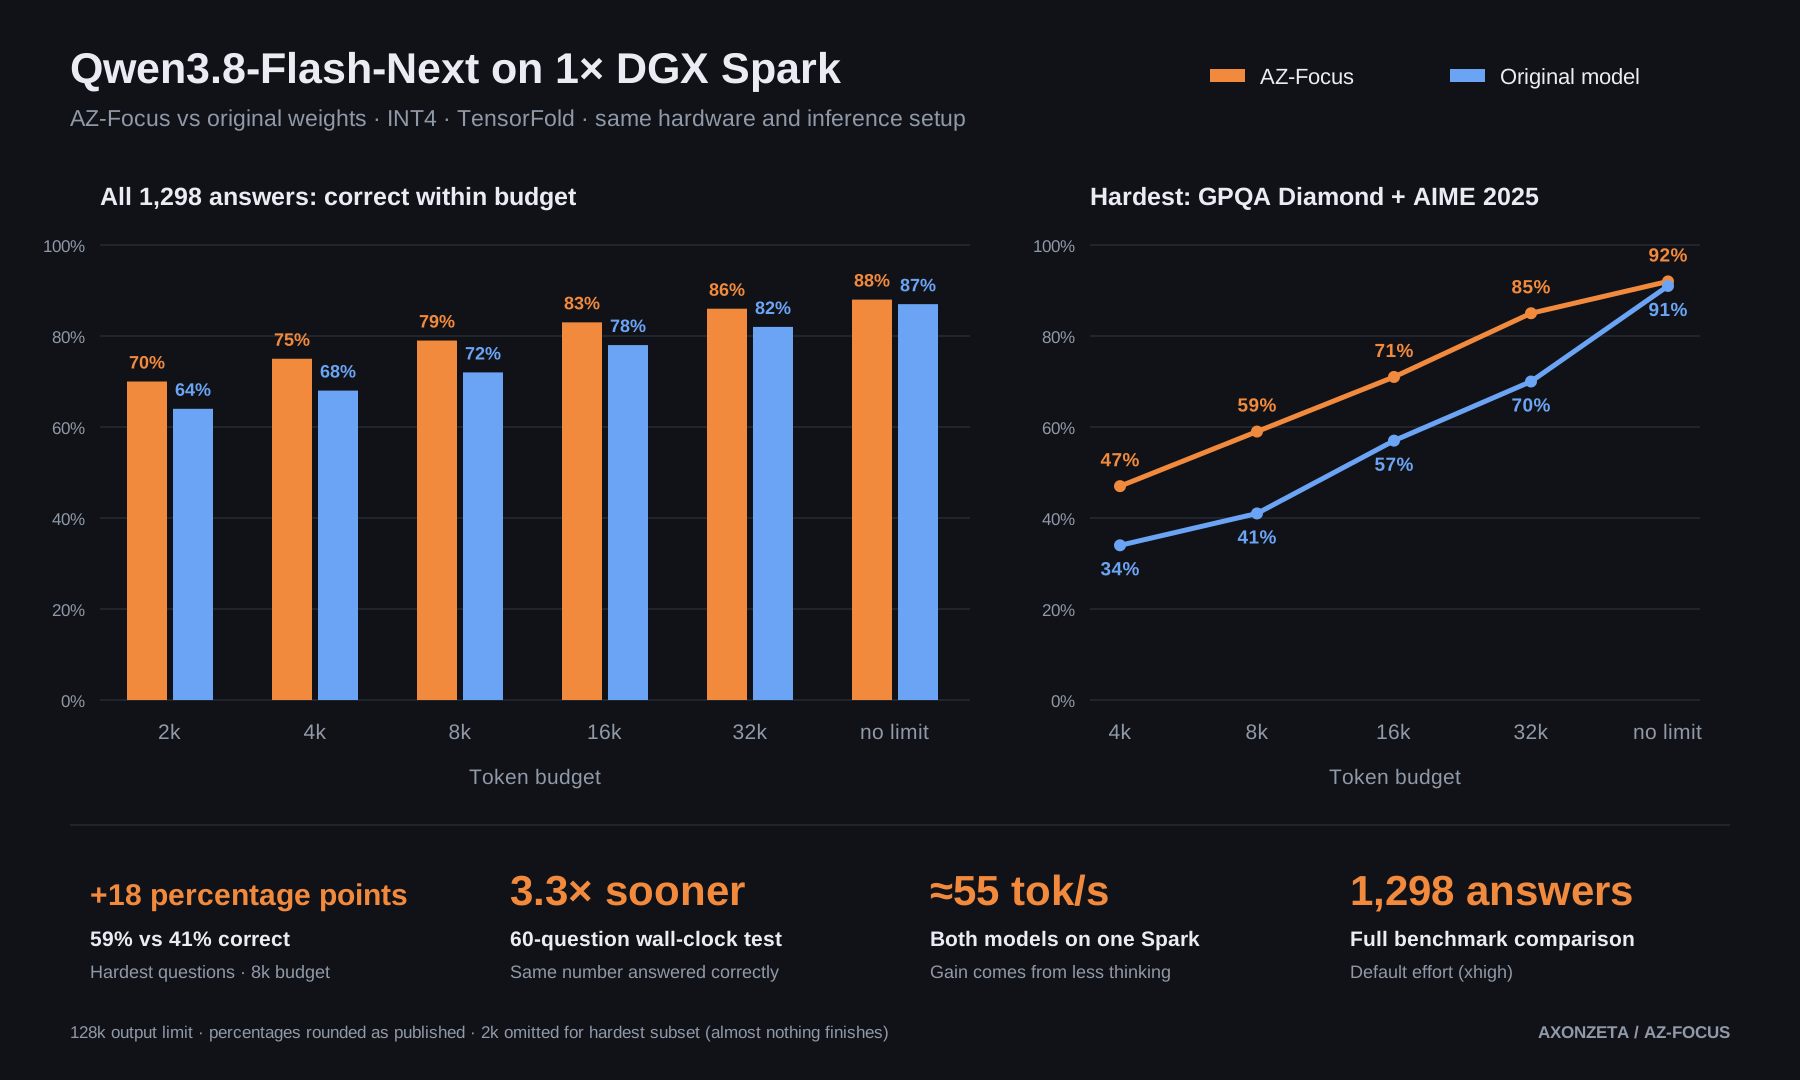
At Qwen3.8-Flash-Next's default (xhigh) effort, AZ-Focus cuts thinking by 35% to 52% across four benchmarks, with accuracy level or up.
More correct answers in the time you have
One DGX Spark, default effort, one request at a time. An answer counts only if it is correct and finished within the time limit.
| Correct within | 15 seconds | 30 seconds | 1 minute | 5 minutes | Whole set |
|---|---|---|---|---|---|
| Base | 63% | 68% | 70% | 77% | 65.7 min |
| AZ-Focus | 68% | 77% | 78% | 83% | 19.7 min |
60 questions (30 MMLU-Pro, 30 BIG-Bench Hard), Mia's TensorFold recipe with MTP drafts, from the one-Spark benchmark; per-question times are in its receipts. No answer hit the output limit.
Same speed, more finished answers
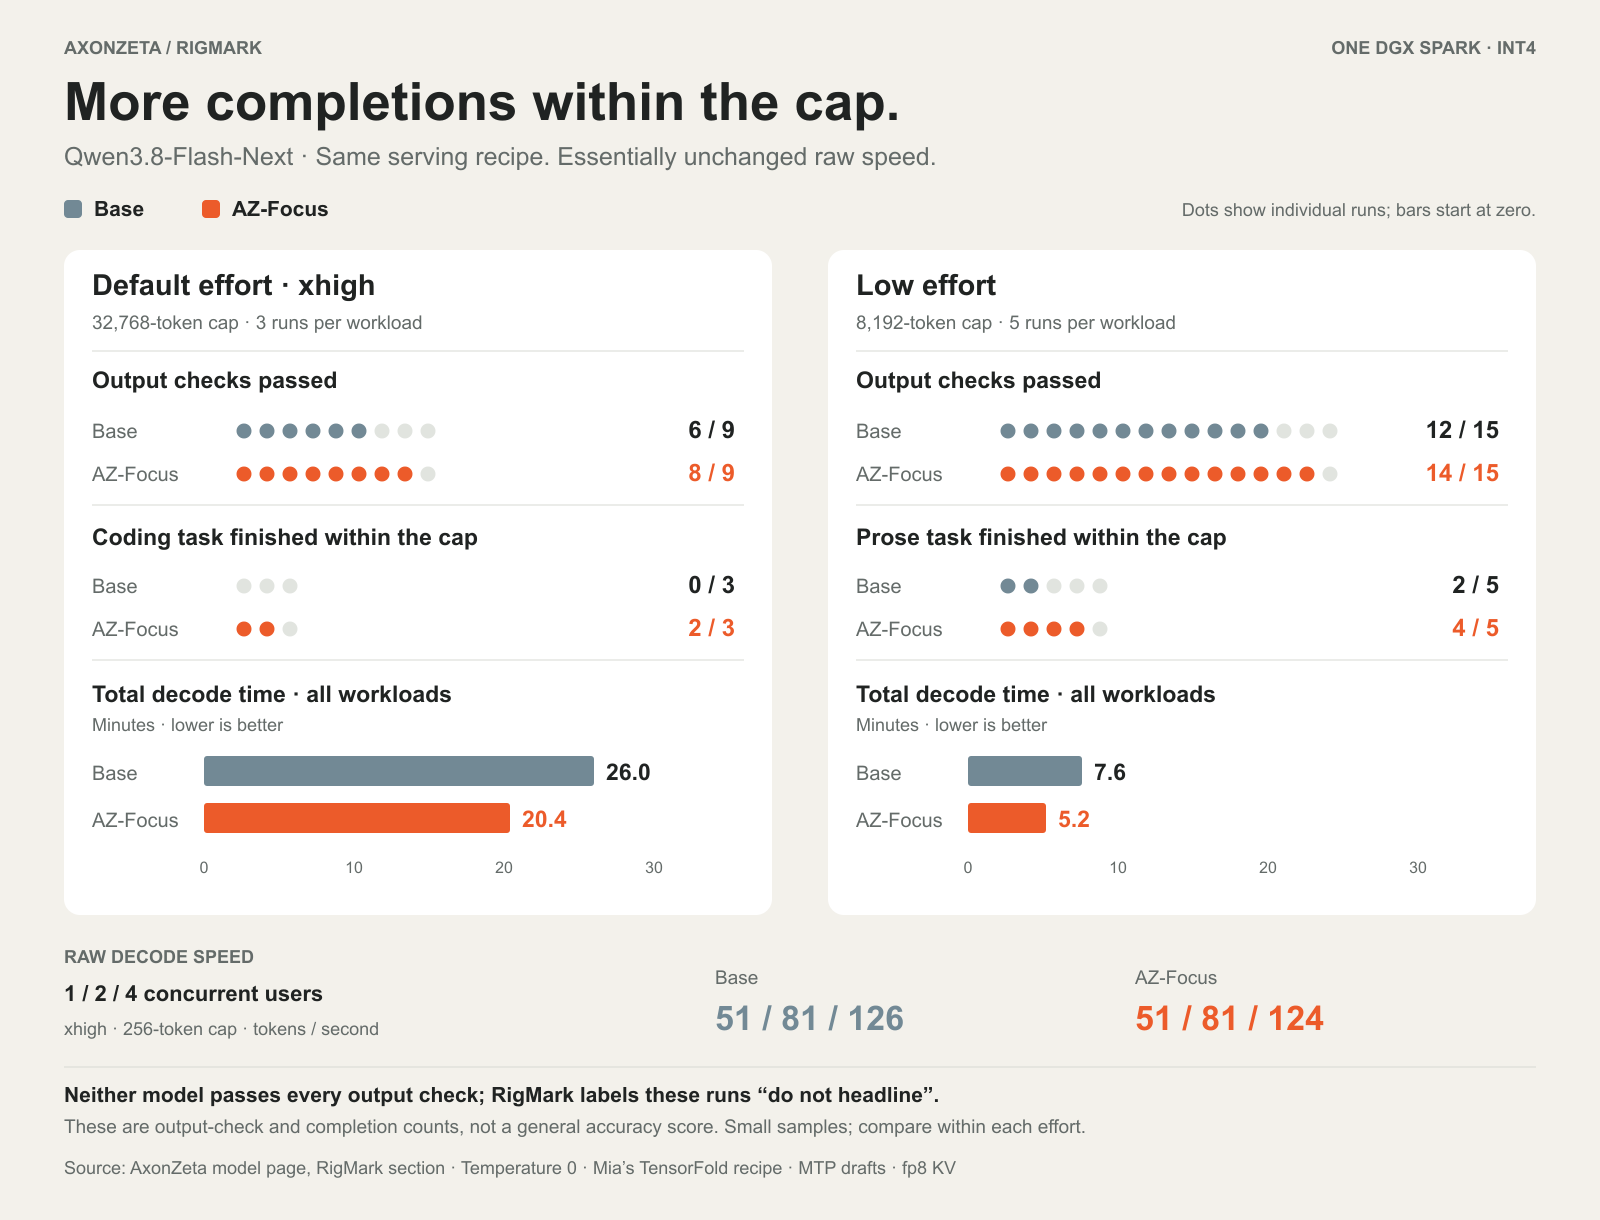
We ran RigMark, the serving benchmark used across DGX Spark recipes, on both models with the same recipe. Raw speed is the same; the difference is how often an answer is finished within RigMark's token cap.
| RigMark, one Spark | Base | AZ-Focus |
|---|---|---|
| xhigh effort (default), 32,768-token cap, 3 runs per workload | ||
| Output checks passed | 6 of 9 | 8 of 9 |
| Coding task finished within the cap | 0 of 3 | 2 of 3 |
| Total decode time, all workloads | 26.0 min | 20.4 min |
| low effort, RigMark defaults (8,192-token cap, 5 runs per workload) | ||
| Output checks passed | 12 of 15 | 14 of 15 |
| Prose task finished within the cap | 2 of 5 | 4 of 5 |
| Total decode time, all workloads | 7.6 min | 5.2 min |
| Speed (both efforts) | ||
| Prefill, 8K / 32K / 64K (tok/s) | 2,563 / 2,518 / 2,434 | 2,546 / 2,515 / 2,430 |
| 1 / 2 / 4 users at once (tok/s, 256-token cap, xhigh) | 51 / 81 / 126 | 51 / 81 / 124 |
At xhigh the base model ran out of tokens on all three runs of RigMark's coding task, thinking to the cap without writing code. RigMark marks every card here "do not headline" because neither model passes all of its output checks. We compare finished answers and total time rather than per-workload rates, which shift depending on which runs hit the cap. Temperature 0, Mia's recipe with MTP drafts and fp8 KV, the public INT4 release. Receipts: Base, xhigh (JSON) · AZ-Focus, xhigh (JSON) · Base, low (JSON) · AZ-Focus, low (JSON).
Across benchmarks, at the default effort
Base vs AZ-Focus, both served the same way: one DGX Spark, Mia's recipe, thinking on, the recipe's sampling, 128k output limit. None of these benchmarks was used to build the model.
| Benchmark | What | Base | AZ-Focus | Thinking, base | Thinking, AZ-Focus | Change |
|---|---|---|---|---|---|---|
| Reasoning & knowledge | ||||||
| MMLU-Pro | 500 questions, 14 subjects | 85.4% | 86.4% | 5,880 | 2,849 | 52% less |
| BIG-Bench Hard | 540 logic & reasoning tasks | 87.6% | 87.4% | 1,962 | 1,059 | 46% less |
| GPQA Diamond | 198 graduate-level science questions | 88.9% | 90.4% | 20,172 | 10,721 | 47% less |
| Maths | ||||||
| AIME 2025 | 30 competition problems, 2 runs | 98.3% | 98.3% | 27,342 | 17,858 | 35% less |
| Coding | ||||||
| SWE-bench Verified | first 100 tasks, agentic (mini-SWE-agent), 2 runs | 97/100 | 96.5/100 | |||
SWE-bench: 97 and 96 vs 97 and 97 (mean shown). Per-answer results for both models are in the receipts.
Best at the default effort
Qwen3.8's default is xhigh, and that's where the hesitation is. At low effort it already thinks briefly; AZ-Focus saves almost nothing there, so use the base model at low.
Agents keep checking
Agentic coding is unchanged on SWE-bench Verified, and so is the number of agent steps: the saving is in reasoning, not in the checks an agent makes before it submits.
Weights only
The change is in the weights: no adapter, runtime patch or extra code. Only the attention and shared-expert output weights differ from the base checkpoint; everything else is byte-for-byte the same.
Use it at the default
At xhigh, the default, AZ-Focus halves the thinking with accuracy up. At low, the base model already thinks briefly and AZ-Focus doesn't help.
One Spark, one line
The INT4 release is a drop-in for Mia's single-Spark TensorFold recipe: point MODEL_ID at it and everything else (MTP drafts, KV cache, context, effort levels) works as in the recipe. It's built on azampatti's INT4-AutoRound checkpoint, which routes each token to 5 experts instead of Qwen's 10 for speed and is healed to stay close to the original; every comparison here is against that checkpoint. For the full 10-expert model there are EXL3 4.05 bpw (one Spark, with Victor Cruz's EXL3 recipe) and BF16 releases: 39% less thinking on our 128-answer set (109 vs 112 correct) and SWE-bench Verified 98 vs 96.
Limitations
- Use the default (xhigh) effort; at low effort use the base model.
- Set an output limit: on 2 of 1,298 answers AZ-Focus kept exploring past 128k tokens without answering (none for the base model); on other seeds it solved both.
- Other languages, very long contexts, vision and multi-hour agent sessions haven't been measured separately yet.
Qwen Community License 1.0, as for the original; note its terms for very large products and for Model-as-a-Service / AI work-assistant businesses. Based on Qwen3.8-Flash-Next by Qwen, with thanks to Intel, Saren-Arterius, azampatti, Mia and Ash Hart.
Want to build on this?
We're an independent AI lab, looking for a few partners to build with at the frontier.